DoTA-RAGDynamic of Thought Aggregation RAG
SIGIR LiveRAG 2025 — Oral presentation
1 SCBX2 SCB 10XBangkok, Thailand
Search the right part of the web
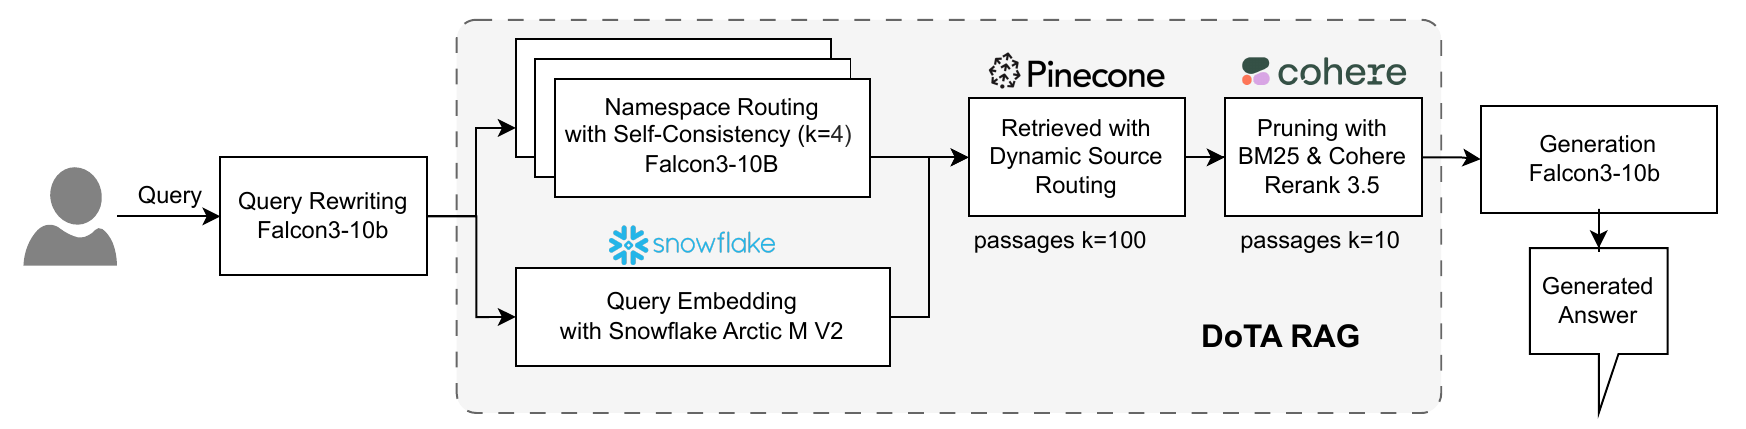
DoTA-RAG combines topic-aware routing with a sequence of retrieval and ranking steps to answer questions over FineWeb-10BT. It targets a practical challenge: finding useful evidence in a large, varied corpus while keeping response time manageable.
Developed for the SIGIR 2025 LiveRAG Challenge, the system uses Falcon3-10B-Instruct for generation and Snowflake Arctic embeddings for retrieval. Its evaluation pairs a diverse internal benchmark with a separate live challenge test.
15Mdocuments in the corpus
500internal benchmark questions
35.63 sper question, final internal configuration
Route first. Retrieve broadly. Refine the evidence.
- Rewrite the question. A low-temperature rewrite corrects noisy wording and misspellings before retrieval.
- Choose the relevant namespaces. Falcon3-10B-Instruct makes four independent topic classifications. Self-consistency voting selects the top two Pinecone namespaces, which are queried in parallel.
- Retrieve and rank. Arctic-embed-m-v2.0 retrieves 100 candidate passages. BM25 narrows these to 20; Cohere Rerank 3.5 selects the final 10.
- Assemble the context. The passages are combined within an 8,000-token budget, with proportional truncation when needed.
- Generate an answer. Falcon3-10B-Instruct answers using the retrieved context and rewritten question.
The paper reports a 92% smaller average search space with routing. In the internal ablation, time per question falls from 100.84 seconds with Arctic-M to 19.01 seconds after routing is added.
Source: paper §2 and Table 3. The final pipeline adds pruning, reranking, and rewriting after the routing-only configuration.
One corpus, many kinds of knowledge
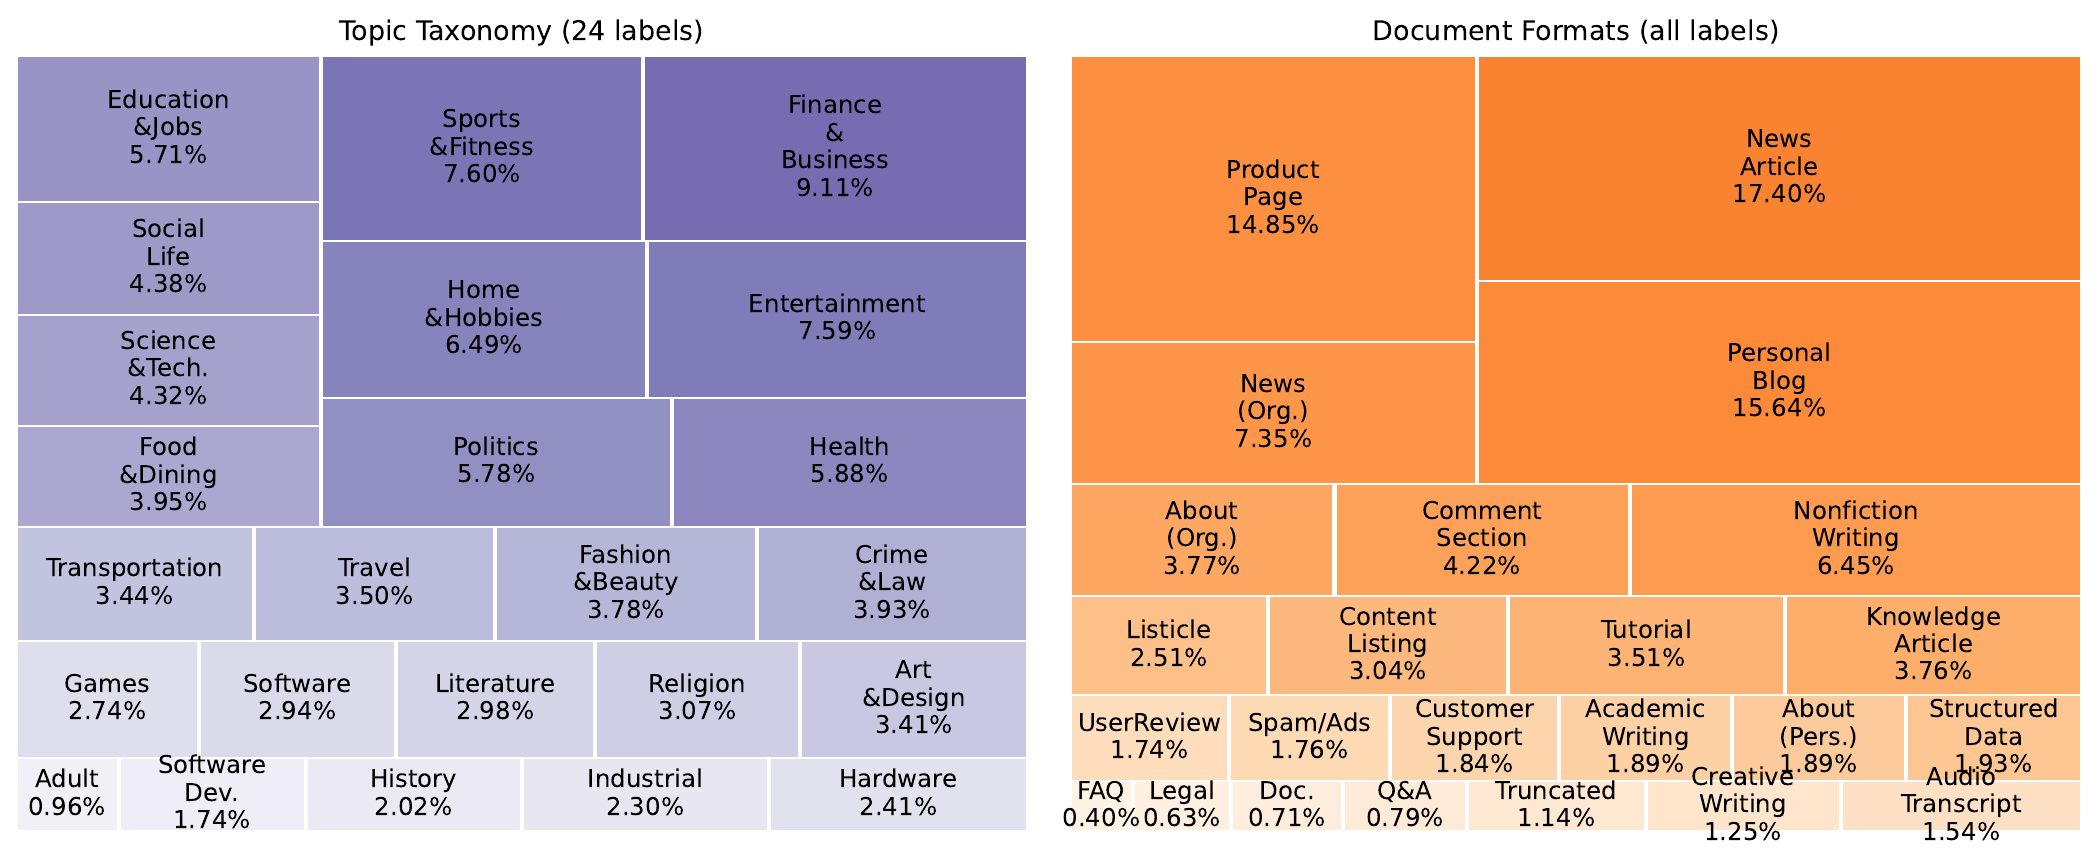
WebOrganizer classifies FineWeb-10BT along two axes: 24 topics and 24 document formats. Topic labels define the namespaces used for routing; the topic–format distribution also informs the internal benchmark’s sampling.
A benchmark built for variety
The 500-question MorganaMultiDocQA benchmark is constructed with DataMorgana and stratified topic–format sampling. It includes single-document and multi-document questions, spanning comparisons, temporal change, procedures, causal explanations, quantities, and verification.
First among industry teams. Fifth overall.
Ped100X / DoTA-RAG brings together researchers from SCBX and SCB 10X. It is the highest-ranked industry team in the supplied standings; the four teams above it represent academic or research institutions.
The industry distinction is also reported in SCBX’s announcement. It describes the team’s placement, rather than a separate award category.
| Rank | Team | Institution | Borda | Correctness | Faithfulness |
|---|---|---|---|---|---|
| 1 | RMIT-ADMS | RMIT, Australia | 7.707 | 1.199 | 0.477 |
| 2 | RAGtifier | L3S Research Center, Leibniz University Hannover, Germany | 7.351 | 1.134 | 0.552 |
| 3 | UDInfo | University of Delaware, USA | 7.240 | 1.201 | 0.623 |
| 4 | Magikarp | Institute of Automation, Chinese Academy of Sciences, China | 7.077 | 1.232 | 0.656 |
| 5 | Ped100X · DoTA-RAGOur team · #1 industry team | SCBX, Thailand | 6.226 | 0.929 | 0.043 |
| 6 | ScaledRAG | University of Massachusetts Amherst, USA | 6.072 | 0.996 | 0.418 |
| 7 | HLTCOE | Johns Hopkins University, USA | 6.019 | 1.070 | 0.341 |
| 8 | Ragmatazz | OpenSource Connections, Germany | 5.471 | 1.012 | 0.519 |
| 9 | PRMAS-DRCA | IISER Kolkata, India | 5.207 | 0.923 | 0.411 |
| 10 | Hybrid Search with Graph | Southwest University, China | 5.077 | 0.875 | 0.316 |
| 11 | RUC DeepSearch | Renmin University of China | 5.067 | 0.969 | 0.388 |
| 12 | Graph-Enhanced RAG | Huawei Technologies, United Kingdom | 4.803 | 0.876 | 0.529 |
| 13 | Emorag | Emory University, USA | 4.683 | 0.891 | 0.557 |
| — | UIUC-RAGents | University of Illinois Urbana-Champaign, USA | — | 0.565 | -0.303 |
| — | UiS-IAI | University of Stavanger, Norway | — | 0.552 | 0.434 |
| — | RAGentA | TU Dresden, Germany | — | 0.836 | 0.200 |
| — | Starlight | Carnegie Mellon University, USA | — | 0.818 | 0.433 |
| — | BagBag | Hefei University of Technology, China | — | 0.694 | -0.911 |
| — | UniClustRAG | Athens University of Economics and Business, Greece | — | 0.685 | 0.460 |
| — | METURAG | — | — | 0.673 | 0.325 |
| — | DeepRAG | New York University, United Arab Emirates | — | 0.566 | 0.098 |
| — | SNU-LDILab | Seoul National University, South Korea | — | 0.517 | 0.103 |
| — | Gravitational Lens | University of Auckland, New Zealand | — | 0.377 | -0.988 |
| — | NoobRAG | TU Dresden, Germany | — | 0.655 | 0.155 |
| — | AugmentRAG-TUD | TU Dresden, Germany | — | 0.533 | 0.656 |
An em dash means no rank or value is provided. Unranked entries retain their source order. These competition results are separate from the internal evaluation below.
Download the complete source CSV · Includes all metrics, affiliations, paper links, and full-precision scores.
Internal evaluation: each stage has a tradeoff
The ablation below uses the internal test set and Claude 3.5 Sonnet as judge. Correctness ranges from −1 to 2; faithfulness ranges from −1 to 1. These are judge scores, not accuracy percentages.
| Configuration | Correctness | Faithfulness | Seconds / question |
|---|---|---|---|
| Baseline | 0.752 | −0.496 | — |
| + Arctic-M | 1.616 | −0.216 | 100.84 |
| + Routing | 1.562 | −0.108 | 19.01 |
| + Pruning | 1.562 | 0.428 | 29.84 |
| + Rerank | 1.652 | 0.672 | 35.20 |
| + Rewrite · DoTA-RAG | 1.478 | 0.640 | 35.63 |
Baseline timing is not reported because its pre-built index is not directly comparable to the authors’ FineWeb-based Pinecone index. Bold values identify the best reported value in each column.
Reranking gives the strongest internal scores. Adding rewriting lowers those scores; the authors retain it to address noisy queries encountered during the live challenge.
Live Challenge Day: a separate evaluation
The paper reports 0.929 correctness and 0.043 faithfulness for the final pipeline on Live Challenge Day. These results come from a different evaluation and should not be compared as another row of the internal ablation.
The authors attribute the low live faithfulness score to an overlooked 300-word output limit. Their subsequent re-evaluation with a tailored Claude judge found faithfulness of 0.702 for uncut answers and 0.336 for capped answers; these diagnostic scores are separate from the official live scores.
Source: paper §4, Table 3.
Featured in
SCBX’s DoTA-RAG places fifth overall and leads industry teams at SIGIR 2025 LiveRAG.
News, press coverage, and social posts about the team’s result, including republications of the SCBX announcement.
 Positioning
 The Story Thailand
- The Story Thailand
 Wealthplus Today
 Motorcarstory
 Biztodaynews
 Siam Business News
- AC News
 BKK Variety
 The Public Post
 BTimesFacebook
 BTimesX
 BTimes
 Brand Leader
 Mitihoon
- Mitihoon
 Turakijintrend
- Blue Chip
 Yaklongtun
 Isra News
 eFinanceThai
 News Connext
 Biz2plus
 TechMoveOn
 Wealthy Thai
 Corehoon
 Power Time Today
 Power Insurtech
 Techsauce
- 7 Stars News
 SCBPress release
- SCBPress release
 SCBXPress release
- SCBXPress release
 SCBXLinkedIn
 Pineapple News AgencyArchive
 Black Bull Biz NewsArchive
Entries marked “Archive” link to the supplied publication listings.
Citation
@misc{ruangtanusak2025dotarag,
  title = {DoTA-RAG: Dynamic of Thought Aggregation RAG},
  author = {Saksorn Ruangtanusak and Natthapath Rungseesiripak and
            Peerawat Rojratchadakorn and Monthol Charattrakool and
            Natapong Nitarach},
  year = {2025},
  eprint = {2506.12571},
  archivePrefix = {arXiv},
  primaryClass = {cs.CL},
  doi = {10.48550/arXiv.2506.12571},
  url = {https://arxiv.org/abs/2506.12571}
}